
Flagship product
Swarm Manager
A single control plane for multi-tenant GPUs, from creating a container through to auditing what ran.
Platform targets
- <60s
- Container ready with SSH
- <30s
- GPU returned to the shared pool (Hibernate)
Core capabilities
Swarm Manager — run the whole GPU cluster from one control plane
Swarm Manager shares the GPUs in one machine across tenants, enforces real quotas, hibernates idle work to return resources, and restores MIG layouts automatically after a reboot.
Contact us →MIG Partitioning
Split a GPU into the MIG profiles the hardware supports so several jobs can share one card.
Smart Hibernate
Pause idle containers, return the GPU to the shared pool and keep the data persistent.
Reboot Recovery
The system is designed to restore the layout within 120 seconds of a reboot.
Same-Node Guarantee
Jobs that use several GPUs are always placed on the same host.
One GPU per Container
Reserve one specific GPU for one container.
The problems infrastructure teams meet every day — and how we handle them
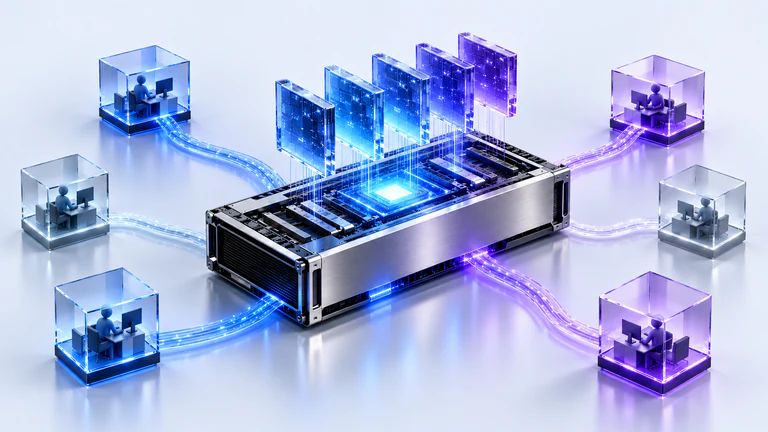
The usual way of using GPUs
- A whole GPU is booked for one job, so memory sits idle and real utilization stays low.
- There is no central quota, so teams compete for the same resources.
- Software licensing for GPU management is a per-card annual cost paid abroad.
The GPU Plexus approach
- Partition cards with MIG and hibernate idle work with Smart Hibernate to return GPUs to the shared pool.
- Five-dimensional quotas (vCPU, RAM, ZFS Storage, GPU count, VRAM) with three permission levels.
- Built by Thai engineers on the NVIDIA Driver standard, reducing reliance on foreign licensed software.
GPU utilization target
75–80%
Capacity increase target
30–50%
Target: from zero to an AI-ready environment in under a minute
No manual scripts — the system runs the steps in order.
- Step 1
Choose an image and embed the SSH key
The OS image is combined with the public key as soon as the create request arrives.
- Step 2
Check five-dimensional quotas
vCPU, RAM, ZFS Storage, GPU and VRAM are checked before allocation.
- Step 3
Two-level smart node selection
General jobs spread across CPU nodes; multi-GPU jobs are locked to one node.
- Step 4
Create the ZFS dataset and attach MIG
A volume is created with its real quota and linked to the MIG profile.
- Step 5
Open Ingress and SSL automatically
A port is allocated from the configured range and the domain is bound with its certificate.
- Step 6
Ready to use
The container is running and reachable over SSH.
Telemetry every 15 seconds
The system records resource usage every 15 seconds.
Three permission levels
- Admin — Create and close accounts, set quotas and see every container.
- Reseller — Share part of its own quota with customers and see only the work it manages.
- User — Use containers within the assigned quota.
Five-dimensional quotas
- vCPU
- RAM
- ZFS Storage
- GPU count
- VRAM
Audit Trail
A 365-day history of significant events.
Sample event names
- container.created
- user.resource_allocated
- user.role_changed
Six core platform modules
Every module works from the same data, so what you see in the portal matches the real state of the cluster.
Container
Create, start, stop, hibernate and wake workloads, with health checks, environment, cron and live logs.
Image
Assemble the OS image with the user’s SSH key, support private registries and .tar imports.
Volume & Storage
A shared volume tree on ZFS with quotas, daily snapshots and backup and restore.
Port & Ingress
Allocate ports from the configured range and attach domains with certificates automatically.
GPU & MIG
Reserve one GPU per workload, apply the supported layout, and report drift after a reboot.
Fleet & Monitoring
Register nodes, watch heartbeats, place work by remaining capacity and collect metrics every 15 seconds.
Engineering transparency
The design choices that make the system predictable and fixable in practice.
Intent separated from actual state
The database holds what the system intends; actual state is read from the cluster and cached briefly to reduce read load.
Spec changes rebuild the container
Changing a specification runs as a fresh container with rollback if any step fails.
Waking against real resources
Waking a container matches a GPU set with enough VRAM, not merely a free host.
Drift is reported, not hidden
When a GPU layout differs from the recorded one, the platform reports it for an operator to decide.
Three delivery models
Choose the model that fits how your organisation already runs infrastructure.
Software License & Subscription
Swarm Manager installed on your own infrastructure (self-hosted / on-premises), licensed per node or GPU per year.
Implementation & Support
Design and installation of AI server infrastructure, software customisation to your requirements, and annual service-level support.
GPU-as-a-Service
Rent containers with GPU and VRAM by quota specification and usage time — suited to demand that changes.
Built for teams that need the most out of every GPU
- 01
Fine-grained GPU sharing
Use MIG to share a card between jobs without booking the whole device.
- 02
Automatic resource reclaim
Hibernate idle work and keep data persistent with ZFS snapshots.
- 03
Real quota control
Five-dimensional quotas and three permission levels are checked before every container is created.
- 04
Runs inside your organisation
Self-hosted licence or managed service, without locking you to a single provider.
- 05
Supported by a Thai team
Built and supported by engineers in Thailand.
Ready to design AI infrastructure that fits your organisation?
Tell our engineers about your challenge and we will help assess the right approach and cluster size.